Sookwan (Andrew) Han
한수관
I am co-founder of Affordance.
News
- Nov 2026 Our paper got into CoRL 2026 Late-Breaking Results ⭐. Poster in Austin, Nov 9 and 10.
- Sep 2026 AER won 1st place of 91 teams in the AMD FPL'26 Agentic FPGA Backend Optimization Contest 🏆
+ Show more
- Jun 2025 I'm going to YC AI startup school. See you in San Francisco
- May 2025 Gave a talk at Balaji NS
- Feb 2025 Our paper, SyncSDE, has been accepted to CVPR 2025! Congratulations to my co-authors Hyunjun and Hyunsoo, remarkably talented undergraduates.
- Aug 2024 Started the ROUND team.
- Jul 2024 One paper is accepted to ECCV 2024 as oral presentation.
- Dec 2023 Joined Republic of Korea Air Force.
- Aug 2023 Won 1st place in 2023 SNU FastMRI challenge.
- Aug 2023 Successfully lead the Diffusion Lecture in Visual Computing Lab. The materials are available here.
- Jul 2023 Two papers are accepted to ICCV 2023 as oral presentations.
Essays
- 죽음이 가치체계의 근원이다 / Death is the source of value system
- 나라의 마지막 희망; 그리고 나아가야할 방향
- 인간관계는 양성 피드백 시스템 / Relationship is a positive feedback system
Progress
Affordance
Data Infra & Hardware for Interactive Physical Intelligence
Human-Robot Interaction
Website: affordance.homes
CoRL 2026 Late-Breaking Results ⭐: affordance.homes/lbr
AER
1st place, AMD FPL'26 Agentic FPGA Backend Optimization Contest
Website: jellyheadandrew.github.io/aer
Contest site: xilinx.github.io/fpl26_optimization_contest
Publications
* equal contribution; † corresponding author
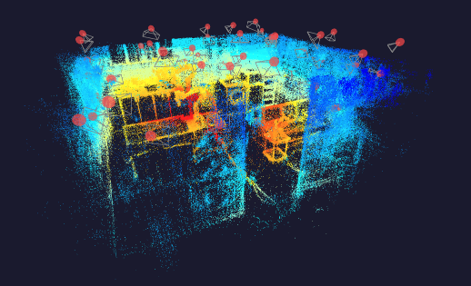
OmniRobotHome: A Multi-Camera Home Platform for Real-Time Human-Robot Interaction
Preprint
[arXiv] [Project Page]
Multi-camera home-replica system for exploring real-time triadic human-robot collaboration.

SyncSDE: A Probabilistic Framework for Diffusion Synchronization
In CVPR 2025
[arXiv] [Project Page]
Probabilistic framework unifying diffusion synchronization.

Beyond the Contact: Discovering Comprehensive Affordance for 3D Objects from Pre-trained 2D Diffusion Models
In ECCV 2024 as Oral Presentation
[arXiv] [Project Page] [Code]
Novel representation that jointly models contact, orientation, and spatial affordances.

Learning Canonicalized 3D Human-Object Spatial Relations from Unbounded Synthesized Images
In ICCV 2023 as Oral Presentation
[arXiv] [Project Page] [Code]
Scalable method for inferring how humans spatially interact with tools and objects.

Chupa: Carving 3D Clothed Humans from Skinned Shape Priors using 2D Diffusion Probabilistic Models
In ICCV 2023 as Oral Presentation
[arXiv] [Project Page] [Code]
3D clothed human reconstruction from single images using diffusion-based carving on SMPL priors.